Hardware Bottlenecks Drive China's Open-Weight Artificial Intelligence Strategy
China has increasingly released its frontier artificial intelligence models under open-weight architectures, allowing users across the world to download, customize, and operate them locally. While presented internationally as a cooperative global public good, this strategy is substantially driven by domestic hardware limitations. United States export curbs initiated in 2022 have restricted Chinese technology entities from securing high-end microchips and advanced manufacturing tools, preventing domestic firms from sustaining the massive cloud infrastructure necessary to serve global web queries directly.
Significance for the UPSC Syllabus
For General Studies Paper 3 (Science and Technology) and Paper 2 (International Relations), this dynamic provides crucial insights into:
Live Test Series
Join thousands of aspirants in our weekly live mock tests. Get real-time ranking and detailed analysis.
- Semiconductor Geopolitics: Demonstrates how technology denial regimes and supply-chain restrictions reshape global software distribution models.
- AI Deployment Models: Contrasts closed proprietary systems hosted via application programming interfaces with open-weight frameworks that support local data sovereignty.
- Compute Architecture: Highlights the operational divergence between concentrated model training and continuously scaling model inference.
Background: Training Versus Inference Compute
Artificial intelligence systems require computational hardware at two distinct operational stages: training and inference. Training constitutes a one-time fixed investment where developers assemble processor clusters to train a base model over several months. Chinese firms have demonstrated the ability to reach model-level parity through stockpiled or export-compliant hardware; for example, DeepSeek trained its V3 architecture using approximately 2,000 H800 chips, compared to an estimated 25,000 chips utilized for GPT-4 and around 16,400 chips for Meta's Llama 3.1.
In contrast, inference represents a continuous computational flow that expands alongside user volume. Serving live user prompts at scale requires vast fleets of graphic processors—OpenAI surpassed one million units in 2025, while Meta aimed for 1.3 million by late 2025. Because export controls deny access to cutting-edge accelerators like the H200 and domestic fabrication remains constrained—such as SMIC's 5nm semiconductor line operating at roughly 20% yield without extreme ultraviolet lithography—Chinese firms cannot host massive application programming interfaces alone. Distributing open weights effectively outsources the immense computational cost of inference to global end-users and client servers.
Reported by The Hindu — International
12th BRICS Parliamentary Forum Held in New Delhi Emphasising Multilateral Dialogue and Reform
Oct 26, 2026
IIT Madras Study Examines Unequal Labour Market Impacts of Artificial Intelligence in India
Oct 26, 2026

Houthi Missile Attacks Target Saudi Infrastructure Amid Escalating West Asian Regional Conflict
Oct 26, 2026
Resolving Pricing and Structural Challenges in India's Sugarcane and Sugar Milling Sector
Oct 26, 2026
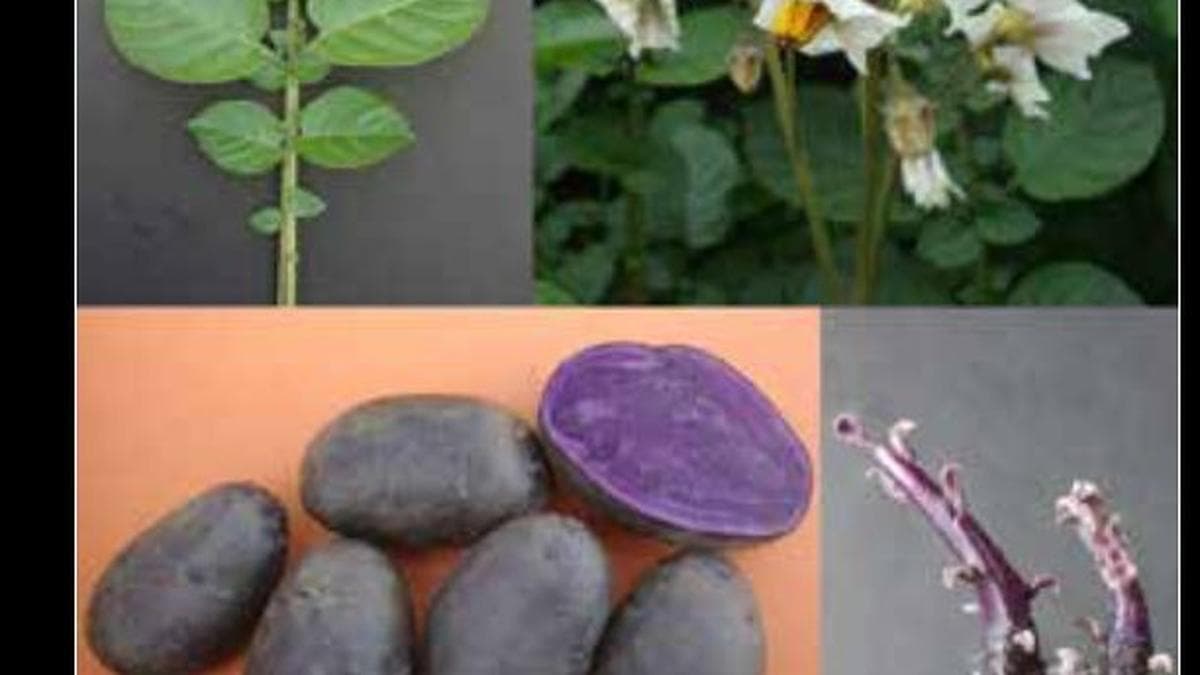
ICAR-CPRI Develops 'Kufri Jamunia' Biofortified Potato to Tackle Hidden Hunger
Oct 26, 2026